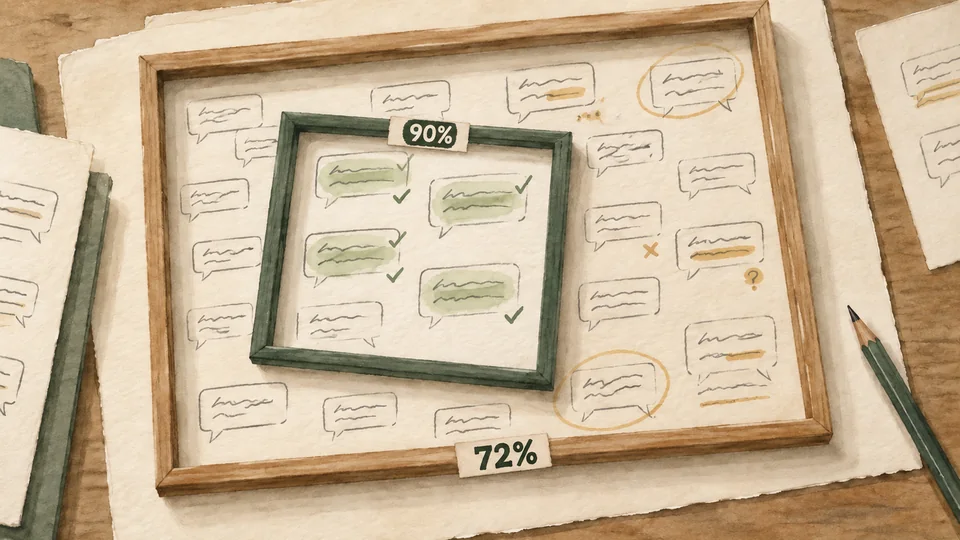
An AI feedback tool can correctly categorise more than 90% of the customer issues it extracts and still miss information that matters to your roadmap. Before using its summaries to influence priorities, you need to understand what was measured, what was excluded, and whether its mistakes would change your decision.
A smartphone UX research paper posted on September 19, 2026, provides a useful example. In one manual validation, classification and sentiment scoring each exceeded 90% accuracy. Yet only 72.2% of the evaluated cases passed the complete process. Both results are correct. They answer different questions.
What the researchers actually tested
The researchers built a system to turn Chinese social-media reviews into structured information about smartphone experiences. Their analysis covered approximately 20,000 reviews across four brands and three platforms.
The system performed three main tasks:
- Extract evidence: Identify the specific experience a person described and what they said about it.
- Assign a category: Place that evidence under a defined topic, such as connection stability or display quality.
- Score sentiment: Assign a satisfaction score from 1, strongly dissatisfied, to 5, strongly satisfied.
The resulting records retained the source review, extracted evidence, category, and score. These supported comparisons of what people discussed and how positively or negatively they described it. Paper, sections 4.1–4.4
A single review can contain several observations. Someone might praise the screen, complain about the battery, and mention unreliable Bluetooth. Treating these as separate pieces of evidence allows each experience to receive its own category and sentiment.
That is why the number of reviews and the number of evaluated cases differ.
Where the 90% and 72.2% results come from
To check the complete process, the researchers selected 233 original reviews covering different brands, platforms, categories, and satisfaction levels. Researchers manually checked the outputs against the original text. They also included reviews for which the system produced no output, allowing them to detect missed evidence.
The results were:
Scroll horizontally to see all three columns.
| Question being checked | Result | Percentage |
|---|---|---|
| Of the extracted units, how many were valid and supported by the review? | 516 of 558 | 92.5% |
| Of the evidence units humans identified, how many did the system extract correctly? | 516 of 569 | 90.7% |
| Among valid extracted units, how many received the correct category? | 475 of 516 | 92.1% |
| Among valid extracted units, how many received the correct sentiment score? | 466 of 516 | 90.3% |
| Across all evaluated cases, how many passed extraction, classification, and sentiment scoring together? | 441 of 611 | 72.2% |
Source: section 4.5.4 and Table 6. Percentages rounded to one decimal place.
The crucial phrase is “among valid extracted units.”
The category and sentiment checks started with the 516 pieces of evidence the system had already extracted correctly. They excluded unsupported extractions and evidence that the system missed.
The complete-process check included those problems. Its 611 cases consisted of the system’s 558 extracted units plus 53 additional evidence units identified by humans but missed by the system. A case passed only when all three stages were correct.
So 92.1% means: “Given a valid extraction, how often was the category correct?” The 72.2% result means: “Across everything evaluated, including missed evidence and invalid extractions, how often did the whole process succeed?”
Neither percentage measures the accuracy of roadmap decisions. The study did not test that.
What survives between a customer’s words and a category?
The paper’s published examples make the transformation easier to understand. The authors paraphrased reported examples to reduce traceability.
One describes intermittent Bluetooth disconnections that annoy the user. It is mapped to connection stability within reliability, with a sentiment score of 2: mild dissatisfaction.
Another describes persistent crashes, an unusable experience, and purchase regret. It is mapped to third-party software stability, also within reliability, with a score of 1: strong dissatisfaction. Table 7
Both belong under reliability, but they describe different experiences. A summary that retains only the broad category loses the distinction between occasional annoyance and a reported inability to use the product.
Preserving the source statement allows a PM to inspect that distinction. The category helps group feedback; the underlying evidence helps explain what needs attention.
A correct interpretation still needs a priority decision
Consider this hypothetical SaaS example:
“The monthly export fails, so our finance team rebuilds the report manually.”
A short feedback-to-decision audit could look like this:
| Step | What we can record |
|---|---|
| Original statement | Preserve the complete comment and its source. |
| Extracted issue | An export failure forces the finance team to rebuild a report manually. |
| Category | Reporting → exports → reliability. This is an illustrative category structure. |
| Sentiment | Negative. A precise intensity score would depend on the scoring guidelines. |
| Proposed priority | Investigate the reporting failure and its impact before assigning a delivery priority. |
“Export problem” captures the feature involved, but drops the manual work the customer reports. Even a faithful extraction leaves several questions unanswered:
- Customer segment: Which type of account is affected, and how does this workflow relate to the customers the product serves?
- Severity: How much work does rebuilding the report require? Does it delay a deadline or introduce errors?
- Reach and recurrence: Is this an isolated failure, or does it affect other accounts and reporting periods?
- Business relevance: Does reliable reporting support a core product promise or an important customer outcome?
The comment identifies a finance team, but does not establish the account’s commercial importance. It describes a monthly export, but doesn’t tell us whether this was a one-off failure or a recurring problem.
Those gaps should remain visible. Assigning a high priority without investigating them would add assumptions that extraction and sentiment accuracy cannot validate.
Sentiment also measures something different from operational impact. A calmly written complaint can describe a serious failure. The customer’s language contributes evidence; the blocked task and its consequences help establish severity.
Which errors would change what you do?
Accuracy treats each checked classification as correct or incorrect. A PM also needs to consider the consequence.
In the hypothetical example, placing the issue under “reporting reliability” rather than “export reliability” might leave the next action unchanged: investigate the failing export. The label is less precise, but the customer problem remains visible.
Other errors could change the decision:
| Possible error | Possible decision consequence |
|---|---|
| Dropping the manual report-rebuilding detail | Underestimating customer effort and severity. |
| Interpreting the comment as a request for a new export feature | Investigating a feature addition instead of an existing failure. |
| Missing the comment entirely | Leaving the problem out of the summary used for prioritisation. |
| Counting several comments from one account as several affected customers | Overestimating the problem’s reach. |
These are hypothetical consequences, not errors demonstrated by the smartphone study.
Some incorrect labels might leave a broader conclusion unchanged. Other errors could concentrate in a particular category and distort its apparent importance. The study’s overall success rate alone cannot tell us which happened or establish that its aggregate findings were wrong.
For a PM, the useful follow-up is: After correcting the analysis, would we choose a different action, urgency, or customer group to focus on?
What to check before a summary influences your roadmap
Start with the evidence supporting a proposed priority. Compare the source statements with the extracted issues and check whether the details driving the recommendation are actually present.
Then read a selection of original feedback independently of the summary, including items that produced no extracted issue. Following links from existing summary entries can reveal misinterpretations, but it cannot reveal an issue that never reached the summary.
A small review can expose weaknesses worth investigating. It does not establish a precise accuracy rate for the entire tool.
The smartphone study’s percentages belong to one research system, domain, and limited validation sample. They are not performance estimates for commercial feedback tools. The authors also caution against transferring their findings across languages, platforms, and markets, or treating public-review patterns as direct measures of retention and commercial outcomes. Sections 6.4–7
Before a summary changes a roadmap priority, the PM should be able to explain which customer evidence supports the change and whether correcting a plausible error would alter the proposed action.